
Compare the stack
Architecture, pricing shape, and the workload each tool is actually built for — not a features matrix copied from a landing page. Every card ends in a verdict.
Cloud Data Stack Cost Estimator
Model real-world monthly bills for Snowflake, Databricks, Google BigQuery, and AWS Redshift with interactive compute, storage, and DBU sliders.
TCO & Unit Economics
Cloud Data Warehouse Cost Comparison
Snowflake vs Databricks vs BigQuery vs Redshift: How to calculate the real 2026 cost of your pipeline.
Verdict: Simulate your exact volume first; architectural features matter less than the shape of the bill.
Warehouse vs lakehouse
Snowflake vs Databricks
SQL concurrency versus Spark and ML. When one engine is enough — and when Iceberg is the contract.
Verdict: Snowflake for SQL-first teams; Databricks for Spark and ML weight.
Lakehouse vs Serverless
Databricks vs BigQuery
The lakehouse engine on GCP compute vs a fully managed serverless SQL warehouse.
Verdict: BigQuery for simple SQL analytics; Databricks for complex Spark / Python ML workloads.
Cost Strategy
AWS Redshift Cost Optimization Guide
Managing Serverless RPUs, Pausing RA3 clusters, and controlling concurrency scaling.
Verdict: Do not set Serverless base RPUs too high, and aggressively monitor concurrency limits.
Credits vs bytes scanned
Snowflake vs BigQuery
Warehouse-hours versus on-demand scans, plus multi-cloud versus GCP gravity.
Verdict: BigQuery for GCP-native serverless; Snowflake for multi-cloud control.
Portable log vs AWS-native
Kafka vs Kinesis
Consumer groups and Connect versus shards, Firehose, and less cluster work.
Verdict: Kinesis for AWS simplicity; Kafka for ecosystem and portability.

Stream processors
Flink vs Spark Streaming
True streaming state and latency versus the engine your batch team already runs.
Verdict: Flink for hard latency and state; Spark for one-engine operations.
Event platforms
Kafka vs Pulsar
Stateless brokers over BookKeeper versus the ecosystem and hiring pool you already have.
Verdict: Pulsar for multi-tenancy and geo; Kafka for everything else.
ELT connectors
Airbyte vs Fivetran
Monthly active rows you cannot fully predict versus infrastructure you have to operate.
Verdict: Fivetran without a platform team; Airbyte when you already run Kubernetes.
Serving vs warehouse
ClickHouse vs Snowflake
Millisecond user-facing analytics versus governance, joins, and elastic concurrency.
Verdict: Serve one sorted table from ClickHouse; keep the warehouse as source of truth.
File formats
Parquet vs ORC vs Avro
Columnar analytics versus row-oriented transport — and why file size matters more.
Verdict: Parquet for queries, Avro for transport, ORC inside Hive.
Table formats
Delta Lake vs Iceberg
Databricks-default versus the shared lake format Snowflake and Spark both speak.
Verdict: Delta inside Databricks; Iceberg for multi-engine neutrality.
Orchestration
Airflow vs Dagster vs Prefect
The industry default, the asset-aware challenger, and the lightest Python option.
Verdict: Airflow to hire for; Dagster for asset thinking; Prefect for light Python.
Vector stores
pgvector vs Pinecone vs Chroma
When Postgres is enough and when a dedicated vector product earns its keep.
Verdict: Start with pgvector; graduate when QPS or scale demands it.
Analytics engines
DuckDB vs Spark (local)
In-process SQL for tens of GB versus a cluster you do not need yet.
Verdict: DuckDB until data outgrows one machine — later than you think.

DataFrames
polars vs pandas
Lazy multi-core expressions versus the ecosystem default everyone knows.
Verdict: polars for new pipeline code; pandas where the ecosystem demands it.
Single node vs cluster
DuckDB vs Spark at the crossover
Where shuffle volume, not raw data size, decides that you finally need a cluster.
Verdict: Stay single-node until shuffle forces the move.
Spark on AWS
Glue vs EMR
Serverless Spark with zero knobs versus full cluster control and spot economics.
Verdict: Glue first; EMR when libraries, versions, or scale force your hand.
Azure analytics
Synapse vs Fabric
The platform Microsoft maintains versus the one it is actually building.
Verdict: New work goes to Fabric; migrate Synapse deliberately, not in panic.
Transformation
dbt Core vs dbt Cloud
CLI inside your orchestrator versus a hosted IDE, managed CI, and per-seat pricing.
Verdict: Core when engineers write the models; Cloud when analysts do.
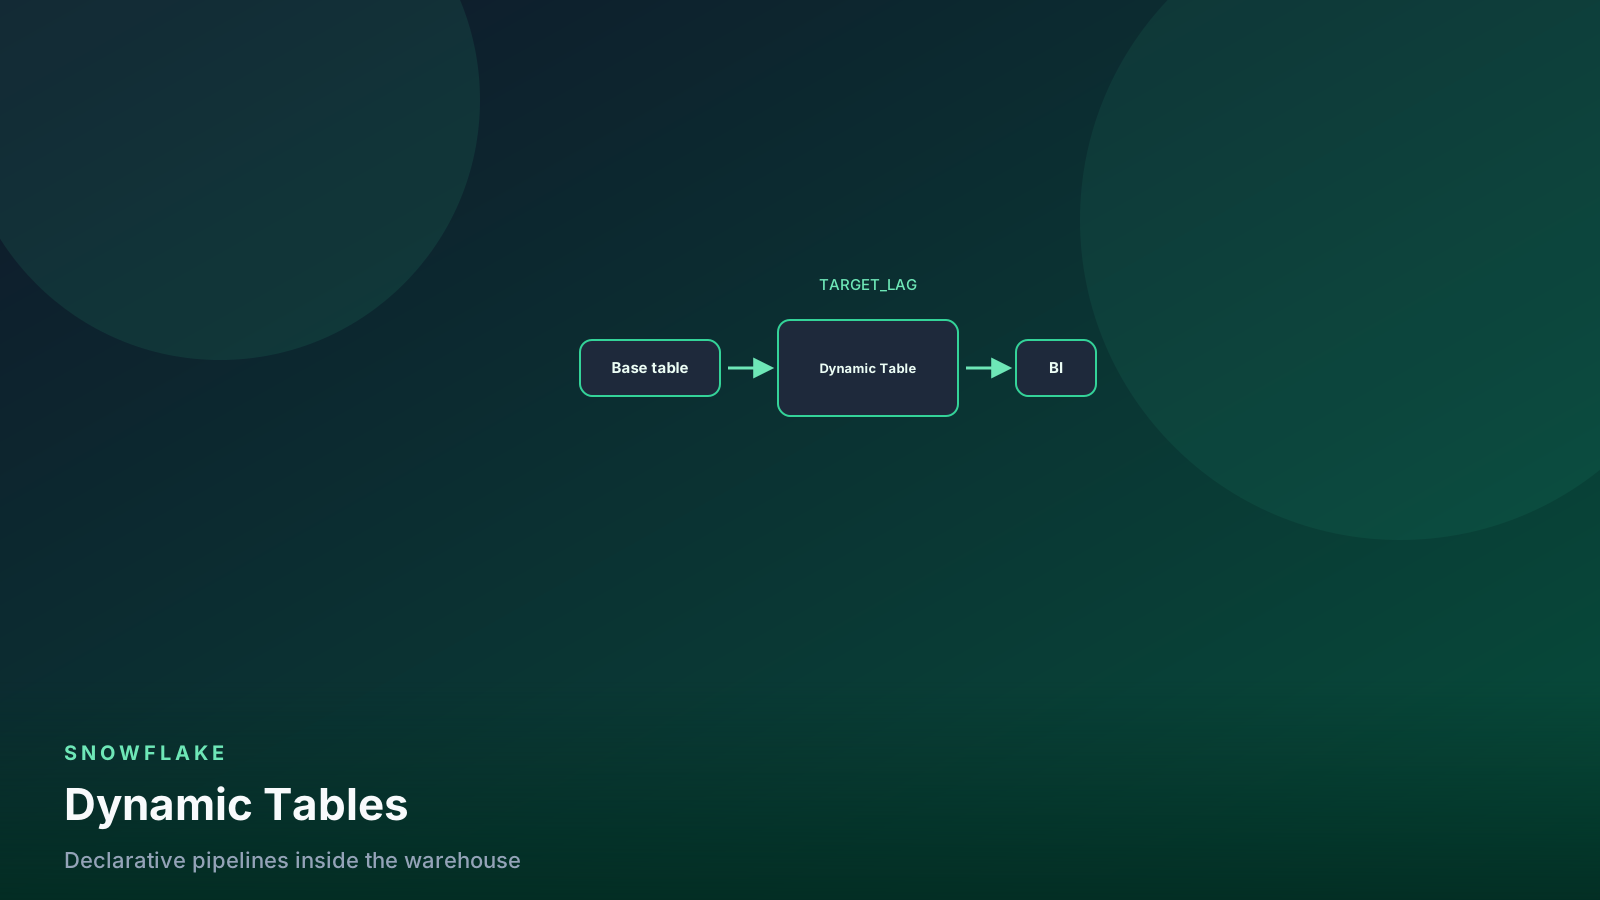
Snowflake pipelines
Dynamic Tables vs Streams & Tasks
Declarative lag versus a stream you own. When dbt still sits in the middle.
Verdict: Dynamic Tables for lag contracts; Streams + Tasks for MERGE control.
AWS warehouse vs multi-cloud
Redshift vs Snowflake
RA3, Spectrum, and WLM versus credits, clones, and a warehouse that is not tied to one cloud.
Verdict: Redshift when you are already deep in AWS; Snowflake when the team wants one bill and clones.
AWS workflows vs DAGs
Step Functions vs Airflow
Per-transition pricing and IAM versus a scheduler you can backfill and hire for.
Verdict: Step Functions for a few AWS-native state machines; Airflow when the graph is a data platform.
Beam vs Spark on GCP
Dataflow vs Dataproc
Portable Beam on a runner that never scales to zero versus the Spark cluster your team already debugs.
Verdict: Dataproc for a Spark bench; Dataflow when event-time windows are the product.
AWS ingest
Kinesis Streams vs Firehose
Shards and consumers versus a managed hose into S3. They are not interchangeable.
Verdict: Streams when you fan out consumers; Firehose when the destination is a landing bucket.
Snowflake compute
Snowpark vs SQL
Python on the warehouse versus the SQL the optimizer already knows how to prune.
Verdict: SQL for warehouses; Snowpark when the logic is already a Python library.
Warehouse grain
Star schema vs one big table
Dimensional joins versus a denormalized fact that is cheap to scan and expensive to change.
Verdict: Star when many grains share dims; OBT for one dashboard that must stay fast.
Deciding between two tools we have not covered?
Tell us what decision you are trying to make. Reader requests regularly become the next comparison we write.
Request a comparison